Taylor-Couette RL Poster
Isaiah Bascom, Min Wang, Yuhe Wang · presented at NASC-RTG
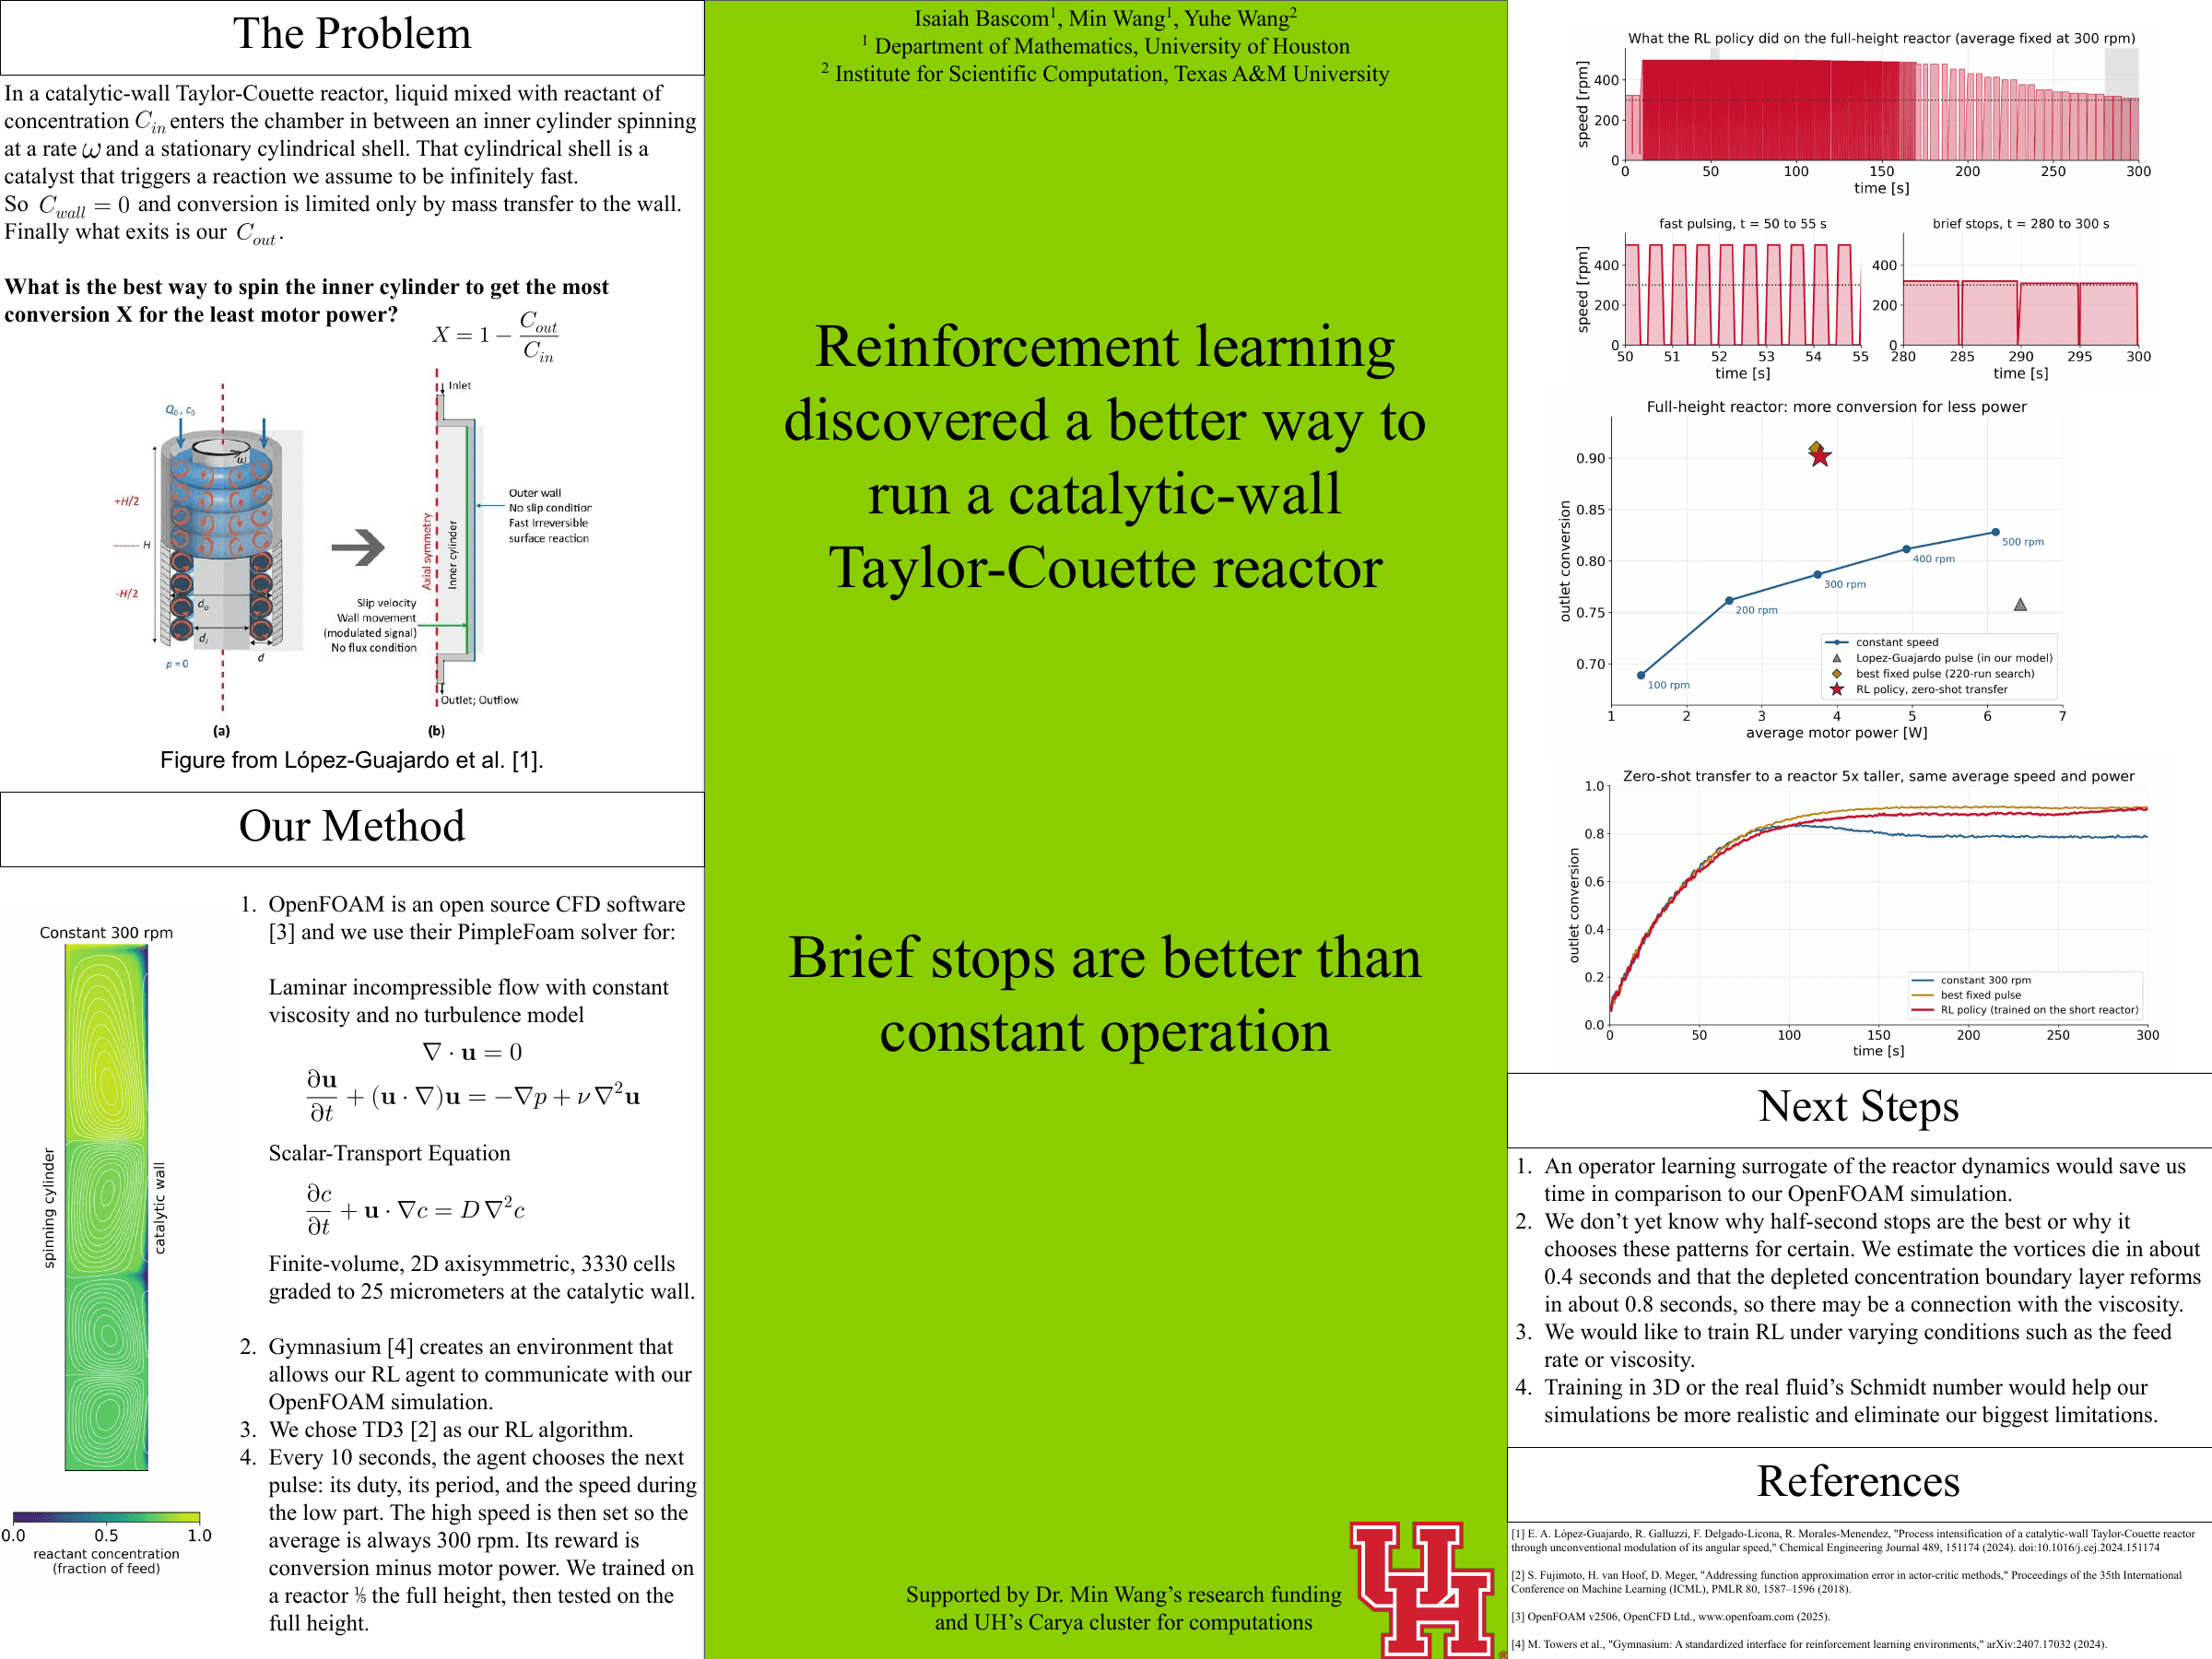
In a catalytic-wall Taylor-Couette reactor, a reactant-laden liquid flows between a spinning inner cylinder and a stationary catalytic shell. The question: how should the inner cylinder be spun to get the most conversion for the least motor power?
We coupled an OpenFOAM simulation of the reactor to a TD3 reinforcement learning agent through Gymnasium. Every 10 seconds the agent picks the next pulse (duty, period, and low speed) with the average held at 300 rpm, and is rewarded for conversion minus motor power. Trained on a reactor ⅕ the full height, the policy transferred zero-shot to the full-height reactor, where it beat constant-speed operation: brief stops are better than constant operation.